
Introduction
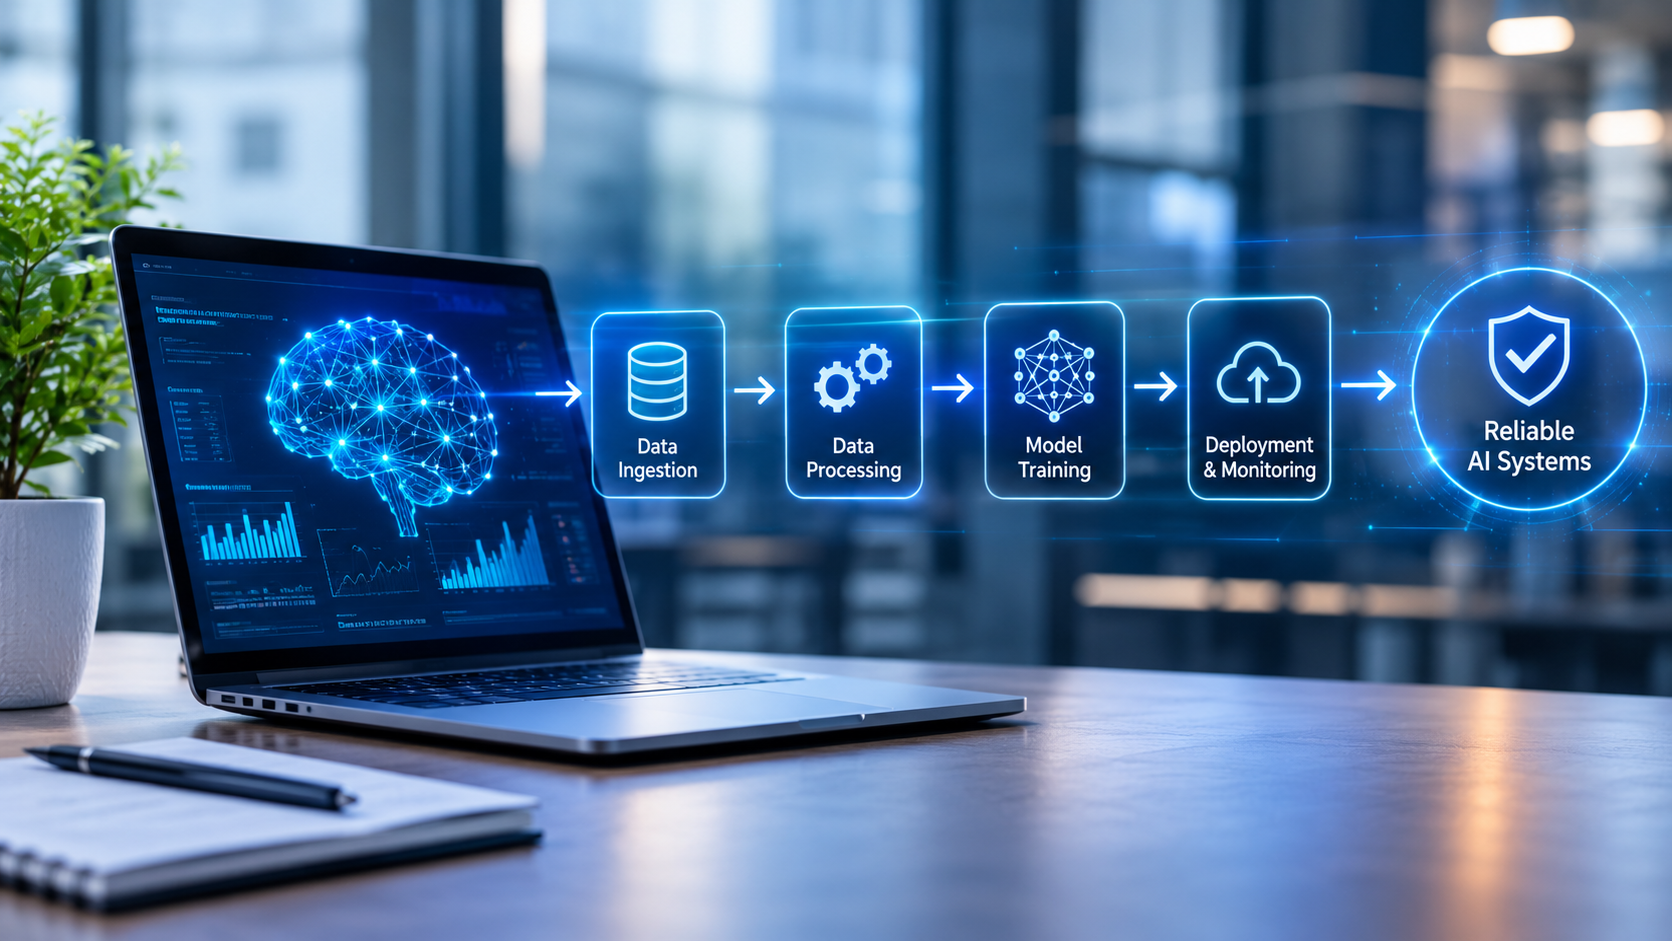
Artificial intelligence is changing how businesses analyze information, understand customers, and make operational decisions. However, developing an accurate machine learning model is only one part of building a successful AI solution. Organizations also need a reliable way to prepare data, train models, evaluate performance, and deploy updates without disrupting existing systems. This is where machine learning pipelines become essential.
A well-designed pipeline connects the different stages of machine learning into a repeatable workflow. It reduces manual effort, improves consistency, and helps data science teams move from experimentation to production more efficiently. As businesses work with growing volumes of data and increasingly complex AI applications, machine learning pipelines provide a practical foundation for building scalable, maintainable, and dependable machine learning systems.
Understanding How Machine Learning Pipelines Work
Machine learning pipelines are structured workflows that automate and coordinate the processes involved in developing and operating machine learning models. These workflows typically include data collection, data preparation, feature engineering, model training, evaluation, deployment, and ongoing monitoring.
Each stage depends on the quality of the preceding stage. For example, incomplete source data can affect feature generation, while poorly selected evaluation metrics can lead teams to deploy models that do not meet business requirements. A connected pipeline helps establish consistent processes and makes these dependencies easier to manage.
Consider a retail company predicting customer demand. Its pipeline may collect historical sales records, combine them with inventory information, prepare the data, train a forecasting model, and evaluate its predictions. Once approved, the model can support inventory planning and replenishment decisions.
The same principle applies across industries, including healthcare, manufacturing, financial services, and telecommunications. By standardizing repetitive tasks, machine learning pipelines allow technical teams to focus more attention on model quality, business problems, and measurable outcomes.
Why Businesses Need Automated Machine Learning Workflows
Manual machine learning processes can work well during early experimentation. However, they often become difficult to maintain when datasets change, models require frequent updates, or multiple teams contribute to the same project.
Automation helps address these challenges. Instead of manually executing every processing and training step, teams can configure workflows that run when new data arrives, scheduled retraining becomes necessary, or specific conditions are met.
Automated machine learning pipelines also improve reproducibility. When data transformations, model configurations, and evaluation procedures are recorded consistently, teams can investigate unexpected results and compare different model versions more effectively.
Another advantage is operational efficiency. Data scientists spend considerable time preparing datasets and coordinating development tasks. Automating repeatable activities can reduce this overhead and allow specialists to concentrate on experimentation, validation, and business interpretation.
Automation does not eliminate the need for human judgment. Teams must still determine whether the data is appropriate, whether the model behaves as expected, and whether its predictions are suitable for the intended application. The objective is to make routine work more reliable while preserving meaningful oversight.
Building Reliable Machine Learning Pipelines Through Data Quality
Data quality has a direct influence on machine learning performance. Missing values, inconsistent formats, duplicate records, outdated information, and biased samples can undermine otherwise sophisticated models.
Effective machine learning pipelines incorporate data validation before training begins. These checks can examine schema changes, acceptable value ranges, missing fields, duplicate entries, and unexpected shifts in data distributions. When a validation rule fails, the workflow can flag the problem rather than allowing unreliable data to move silently into production.
Feature engineering is another important consideration. Models often depend on transformed variables that represent useful patterns in raw data. Consistent feature generation helps ensure that training and production environments apply compatible transformations.
For instance, a fraud detection model may use transaction amounts, account activity, and transaction frequency to identify suspicious behavior. If these features are calculated differently during training and production, prediction quality may decline.
Maintaining clear data definitions, versioning important datasets, and documenting transformations helps organizations create trustworthy workflows. These practices also support troubleshooting because teams can identify which data and processing steps contributed to a particular model version.
Connecting Machine Learning Pipelines to MLOps
Developing a model is different from operating it reliably over time. Production environments introduce challenges involving deployment, monitoring, security, version control, and changing business conditions. Machine learning operations, commonly called MLOps, provide practices for managing these responsibilities.
Machine learning pipelines form an important part of an MLOps strategy by connecting model development with production operations. They can automate testing, package approved models, coordinate deployments, and record information needed for auditing and troubleshooting.
Continuous integration and continuous delivery practices can also improve the release process. Before a model reaches production, automated checks may verify code quality, test data transformations, evaluate model performance, and confirm that deployment requirements have been met.
However, a successful pipeline requires more than automation tools. Teams need clear approval processes, appropriate access controls, documented responsibilities, and defined criteria for releasing model updates.
Organizations should select tools according to their existing infrastructure, technical capabilities, regulatory requirements, and workload characteristics. A straightforward workflow may require only a limited set of services, while a large enterprise environment may benefit from centralized orchestration and comprehensive experiment tracking.
Monitoring Model Performance After Deployment
Machine learning models can lose effectiveness as real-world conditions change. Customer preferences evolve, economic conditions shift, equipment wears down, and patterns in incoming data may differ from historical observations.
This makes monitoring an essential component of production-ready machine learning pipelines. Teams should track operational indicators such as processing failures, prediction latency, resource consumption, and data availability. They should also evaluate model-specific measures, including prediction errors, precision, recall, or other metrics appropriate to the use case.
Data drift occurs when the characteristics of incoming data change. Model drift, often discussed alongside concept drift, concerns changes that reduce the relationship between model predictions and actual outcomes. These issues are related but not identical, so monitoring should reflect the specific risks of each application.
When performance deteriorates, teams may investigate the underlying cause, review recent data changes, retrain the model, or restore a previously approved version. Retraining should not happen blindly. New models need appropriate evaluation to confirm that they offer meaningful improvements without introducing unacceptable risks.
A structured monitoring process helps organizations respond to changing conditions while maintaining accountability for automated decisions.
Improving Scalability and Governance
As machine learning adoption expands, organizations may need to manage hundreds of datasets, multiple model versions, and workflows running across different environments. Without consistent standards, these processes can become difficult to coordinate.
Scalable machine learning pipelines help teams reuse established components, standardize development practices, and manage workloads more efficiently. Shared templates and documented interfaces can reduce duplication while allowing individual projects to retain the flexibility they require.
Governance is equally important. Organizations should maintain records of training data sources, model versions, evaluation results, deployment approvals, and significant changes. Access controls and secure handling of sensitive information should be built into the workflow rather than added after deployment.
For applications involving personal information, financial decisions, healthcare, or other high-impact areas, additional review may be necessary. Human oversight, explainability, fairness assessments, and documented risk controls should reflect the potential consequences of model errors.
Good governance does not need to slow innovation. When requirements are clear and integrated into development processes, teams can identify problems earlier and release changes with greater confidence.
Conclusion
Machine learning success depends on more than selecting an effective algorithm. Organizations need dependable processes that connect data preparation, model development, deployment, and continuous improvement.
Well-designed machine learning pipelines make these processes more consistent, repeatable, and scalable. By combining data validation, workflow automation, MLOps practices, performance monitoring, and responsible governance, businesses can build systems that respond to changing requirements without losing operational control.
The most effective approach begins with a clearly defined business problem and a workflow suited to its complexity. As requirements evolve, organizations can improve their pipelines incrementally, strengthening reliability and accountability while creating a sustainable foundation for machine learning at scale.
 Kuldeep Singh
 Jack Cannan
 Saransh Agarwal